Netdata vs Prometheus and Grafana for One Home Server: When the Full Monitoring Stack Is Overkill
Jesse Cole
October 13, 2026
Every homelab eventually gets the urge to graph everything. Usually it starts with a slow container, a disk that filled overnight, or a fan that sounded louder than usual. The internet’s answer is almost always Prometheus and Grafana, because that is what runs at work and what every tutorial shows. For one home server, it is often the wrong answer, or at least the answer to a question you have not asked yet.
I spent years as an SRE, where Prometheus was the right tool, and I have run both setups at home. This piece is about a single machine: one mini PC, NAS or old desktop running your containers. At that scale, the question is not which tool is more powerful. It is which one tells you what is wrong with the least work and the least overhead.
Start with Netdata, graduate to Grafana
For one home server, start with Netdata. You install one thing and get hundreds of useful charts, sensible alerts and per-second detail within minutes, with almost no configuration.
Move to Prometheus and Grafana when you have several machines to watch, want months of history, want to graph metrics from your own apps, or want to learn the stack because you use it at work. Those are good reasons. “Everyone uses it” is not.
One agent versus a set of building blocks
These are not two versions of the same product. They take opposite approaches.
Netdata is an agent that does everything on the machine it watches. It collects metrics every second, discovers running services on its own, stores the data locally, draws the dashboards, and fires alerts from a large set of preconfigured rules. Install it, open the dashboard, and you are looking at CPU, memory, disk I/O, network, containers, and whatever services it found, such as databases and web servers.
Prometheus and Grafana are building blocks. Prometheus is a time-series database that scrapes metrics from “exporters” on a schedule: node_exporter for the operating system, cAdvisor for containers, others for each service. Grafana draws dashboards from that data. Alertmanager, a third component, routes alerts. You choose what to collect, how often, how long to keep it, and what each dashboard shows. Nothing appears until you set it up.
| Netdata | Prometheus + Grafana | |
|---|---|---|
| Setup | One install, auto-discovery | Several containers plus exporters and configuration |
| Time to useful charts | Minutes | An afternoon, more with alerts |
| Default detail | Every second | What you set, typically every 15–60 seconds |
| Dashboards | Built in, ready-made | Grafana, build or import your own |
| Alerts | Hundreds of rules preconfigured | Write your own rules, route with Alertmanager |
| History | Local, tiered by detail | As long as you configure and have disk for |
| Multiple machines | Possible, best through Netdata Cloud | Built for it |
| Metrics from your own apps | Supported, less natural | The core use case |
Setup: one install versus a small project
Netdata’s install is a single script or a single container. A minute later the dashboard is up, and it has already found your Docker containers, your disks, and any common services running on the box. For someone who wants to know why the server felt slow last night, that matters more than anything else in this comparison.
A working Prometheus and Grafana stack is a small project. At minimum you run Prometheus, Grafana, node_exporter and cAdvisor, and you write a Prometheus configuration listing what to scrape. Then you add a data source in Grafana and import a dashboard; the community “Node Exporter Full” dashboard is the usual starting point. Alerts need rules and an Alertmanager with somewhere to send them. None of this is hard if you have done it before. If you have not, plan an afternoon, and expect to revisit it.
That effort is not wasted. It is the price of control. But on one machine you pay it before you get a single useful chart, and many home setups stall halfway, with Grafana running and no alerts configured.
What you see on day one
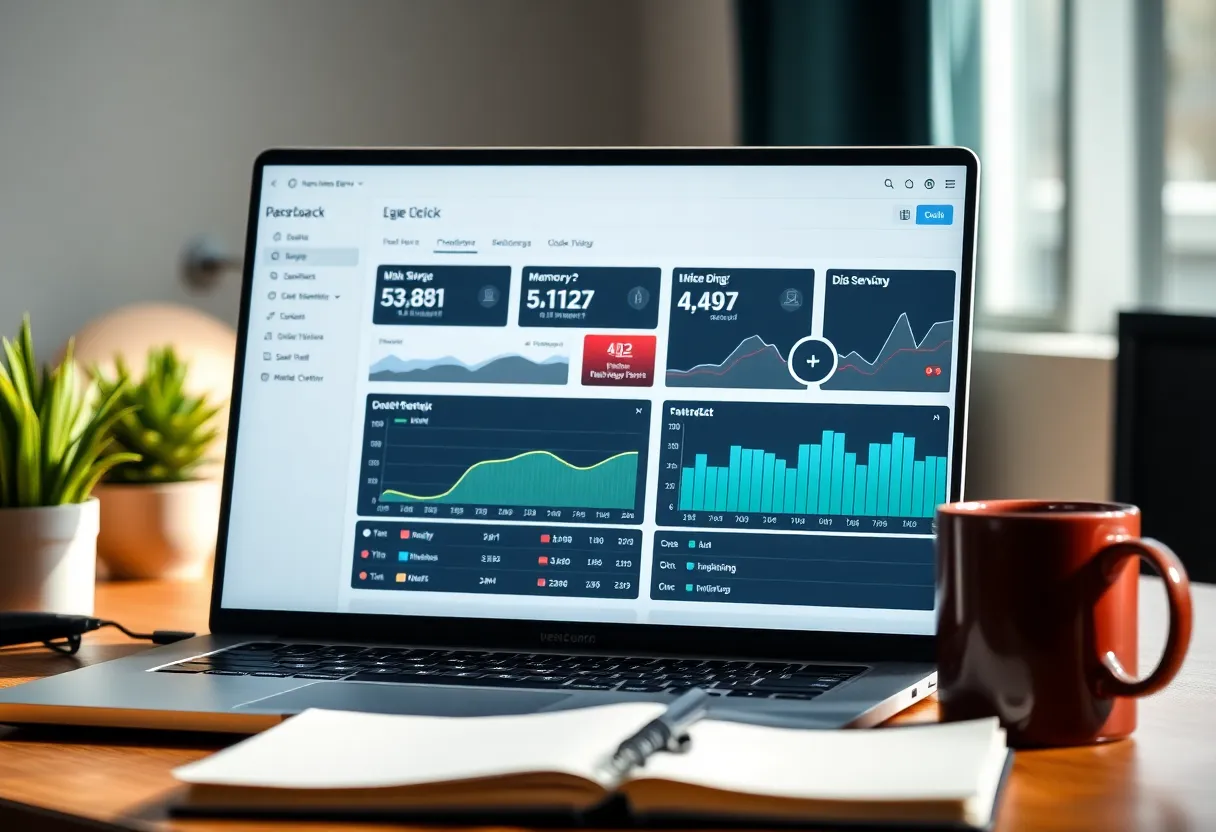
Netdata’s dashboards are dense. Every chart updates every second, and there are a lot of them. That per-second detail is genuinely useful for the problems you actually have at home: a backup job that saturates the disk for ninety seconds, a container that spikes CPU every few minutes, a network transfer that stalls. Fifteen-second averages smooth exactly those spikes away.
The downside is that Netdata shows you everything, whether or not it matters. New users often feel buried. Its newer interface tries to group and summarise, which helps, but it is still built for exploring rather than glancing.
Grafana is the opposite. You see only what you chose to put on the dashboard, laid out the way you want. A well-made Grafana dashboard for your server can answer “is everything fine?” in a two-second glance in a way Netdata’s never quite does. But you have to build or import it, and an imported dashboard is someone else’s idea of what matters.
Alerts: preconfigured versus written
Netdata ships with hundreds of alert rules already on: disk filling up, high load, memory pressure, packet drops, failing services it detected, and more. Out of the box, that catches real problems. It also produces some noise, and you will want to silence a few alerts that do not matter on your machine. Sending alerts to your phone takes a little setup: email, or one of the supported notification services.
Prometheus alerting is precise and entirely yours. You write rules in PromQL, such as “disk will be full within four hours at the current rate”, and route them through Alertmanager to wherever you want. That is powerful, and alerts on rates of change are better than simple thresholds. But until you write them, there are no alerts at all.
Whichever you pick, remember the obvious failure: a monitor on the same machine goes down with the machine. Netdata cannot tell you the server is off if Netdata is on the server. Something outside has to check that the box is reachable, which is the question of which monitor has to live on a different machine from the one it watches.
Resource use on a small box
Neither is free. On a modest mini PC or NAS, both setups use a noticeable slice of resources, and the trade-offs are different.
Netdata collects a lot of metrics every second, which costs some CPU continuously. You can cut that a long way by lowering the collection frequency and disabling collectors you do not need. It stores history locally in tiers, with full detail for recent data and coarser summaries further back, so disk use is bounded and you can tune it.
A Prometheus stack is several processes. Prometheus itself uses memory in proportion to how many metrics you collect, Grafana is a web app, and each exporter is small but adds up. At a 30–60-second scrape interval on one machine it is light. Push the interval down and add many exporters, and it grows.
On something as small as a Raspberry Pi, both can feel heavy. There, an even lighter tool may be the better fit, and it is worth asking whether Beszel is enough on its own before you install either of these.
History and growth
This is where Prometheus starts to earn its complexity. You decide how long to keep data, and on a disk of reasonable size months of history for a few machines is easy. With Grafana you can compare this month’s disk growth with last month’s, or see whether a container’s memory use has crept up since an update.
Netdata keeps history too, but its strength is the recent past in fine detail. It is excellent for “what happened at 3 a.m.?” and less natural for “how has this changed over six months?”.
More machines change the picture as well. One Prometheus can scrape a dozen hosts, and one Grafana dashboard can show them all side by side. Netdata handles several machines best through Netdata Cloud, its hosted service, which brings the agents together in one view. The free tier is limited, and some people would rather keep a homelab entirely local. A word on licensing, too: the Netdata agent is open source, but its newer dashboard is not open source in the same way. For most home users that changes nothing, but if fully open tooling matters to you, check before you commit.
Finally, your own software. If you write services and want to graph their internal numbers, such as jobs processed, queue length or request latency, Prometheus is the standard. Most languages have libraries to expose metrics in its format. Netdata can collect them too, but this is the case Prometheus was built for.
A sensible path for one server
You do not have to choose once and forever. A path that works for most home setups:
- Install Netdata first. Spend a week looking at it. Silence the alerts that do not matter, and set up notifications for the ones that do.
- Add an outside check that the server is reachable, from another machine or a hosted uptime service, because Netdata cannot report its own host being down.
- Move to Prometheus and Grafana when you hit a real limit: a second or third machine, a need for months of history, or metrics from your own code.
- When you switch, keep it small. Start with node_exporter and cAdvisor at a 30–60-second interval, import one dashboard, and write three alerts you actually care about: disk filling, a container restarting in a loop, and the host unreachable.
Matching the tool to the homelab
Netdata is enough when:
- You have one server and want to know what is wrong with it today, not build a monitoring platform.
- You value per-second detail for short spikes.
- You want useful alerts without writing any rules.
The full stack pays off when:
- You have, or soon will have, several machines to watch.
- You want months of history and dashboards built around your own questions.
- You want to graph metrics from your own applications.
- You want to learn the stack for work, which is a perfectly good reason to over-engineer a homelab.
The worst setup is the half-finished one: a Grafana instance with a pretty dashboard and no alerts, watching a server you only check after something has already gone wrong. For one box, Netdata gets you to a working, alerting setup in minutes. Grow into the bigger stack when the homelab does.